
Guest post by Volker Hillmann.
Before you read this
“If a model can write the code, why would anyone still learn to write it?” You may have heard some version of that in the past six months, usually from someone with no stake in the answer.
Volker Hillmann has a stake, and unexpectedly, his answer isn’t as defensive as you’d expect from someone who has been writing C+ since Turbo C++ in 1991. He doesn’t argue that generated code is bad. He argues that even if “it compiles” and even if “the tests are green”, were never the standard in the first place.
If you only have ten minutes, read “The false productivity of AI boilerplate.” It’s his account of why assistants tend to generate at the wrong level of abstraction, and why the speed you feel in the first hour is a debt you accrue for later when the duplication has to be compressed back out of the codebase.
This was first published on LinkedIn in June 2026 and is republished here with Volker’s permission. We collaborated with Volker as a sister company of Embarcadero, of which he is an MVP. His story encapsulates a story we’ve been writing about for a year and we want to share it with the VA community too.
Volker Hillmann’s article begins here.
We are living through a strange moment in the history of software. For the first time, it seems plausible that machines can not only execute programs, but also write them, explain them, test them, repair them and, in carefully bounded cases, even help prove properties about them. From this observation a seductive story has emerged: if AI can write code, humans no longer need to learn coding. If AI knows syntax, generates tests and corrects compiler errors, then people can finally stop dealing with programming languages and focus only on solving problems.
This story sounds modern, liberating and efficient. It promises access, speed and productivity. It also contains a serious misunderstanding.
Programming was never merely the act of typing syntax. Programming is the path by which vague intentions become precise models. It is the discipline of turning a problem into structure: types, states, data flows, invariants, responsibilities, constraints and architecture. It is the ability to shape a system so that it not only works today, but can still be understood, verified, extended and maintained tomorrow. Whoever reduces programming to code generation mistakes the visible activity for the invisible discipline behind it.
This essay argues for a different conclusion. AI does not make programming education obsolete. It makes it more urgent. The more easily code can be generated, the more important it becomes to understand what code means, what architecture it creates, what assumptions it hides and what kinds of errors it makes impossible or merely postpones. The central issue is not whether AI can produce code. It can. The central issue is whether we still have enough people who can judge whether that code is good.
The old mistake: measuring productivity by lines of code
Long before AI entered the discussion, it was already a poor idea to measure a programmer’s productivity by the number of lines of source code written. A programmer who spends a day thinking, looking out of the window, appearing absent minded and then writing only a few lines of code may easily be more productive than someone who fills several files with immediate implementation. The first programmer may have found the right abstraction. The second may have merely implemented symptoms.
This is not romanticism. It is a practical fact of software engineering.
Good software is not produced by maximizing text. It is produced by reducing accidental complexity and expressing essential structure. A few well placed lines can remove an entire class of errors. A carefully designed interface can eliminate dozens of special cases. A better type can prevent invalid states. A small architectural correction can make thousands of later lines unnecessary. A programmer who thinks before writing may produce less visible output, but more resilient, maintainable and extensible software.
This was true before AI. AI now makes the old mistake more tempting.
AI systems often impress because they produce a large amount of source code very quickly. We see screens fill with functions, classes, tests and explanations, and we instinctively say: this is productivity. But that reaction is dangerous. We are impressed by speed and volume, although both were already bad metrics. AI appears productive because it is optimized to generate plausible text, and source code is a form of text. It can quickly produce something that looks complete. It can create activity. It can create momentum. It can create the feeling that progress has occurred.
But software engineering is not the production of source text. It is the production of structure.
If an AI writes twenty functions where a good model would require two concepts, one generic data flow and a small set of composable operations, then the AI has not been productive in the deeper sense. It has produced surface. It may have produced working surface. It may even have produced tested surface. But it has not necessarily produced architecture.
That distinction is central.
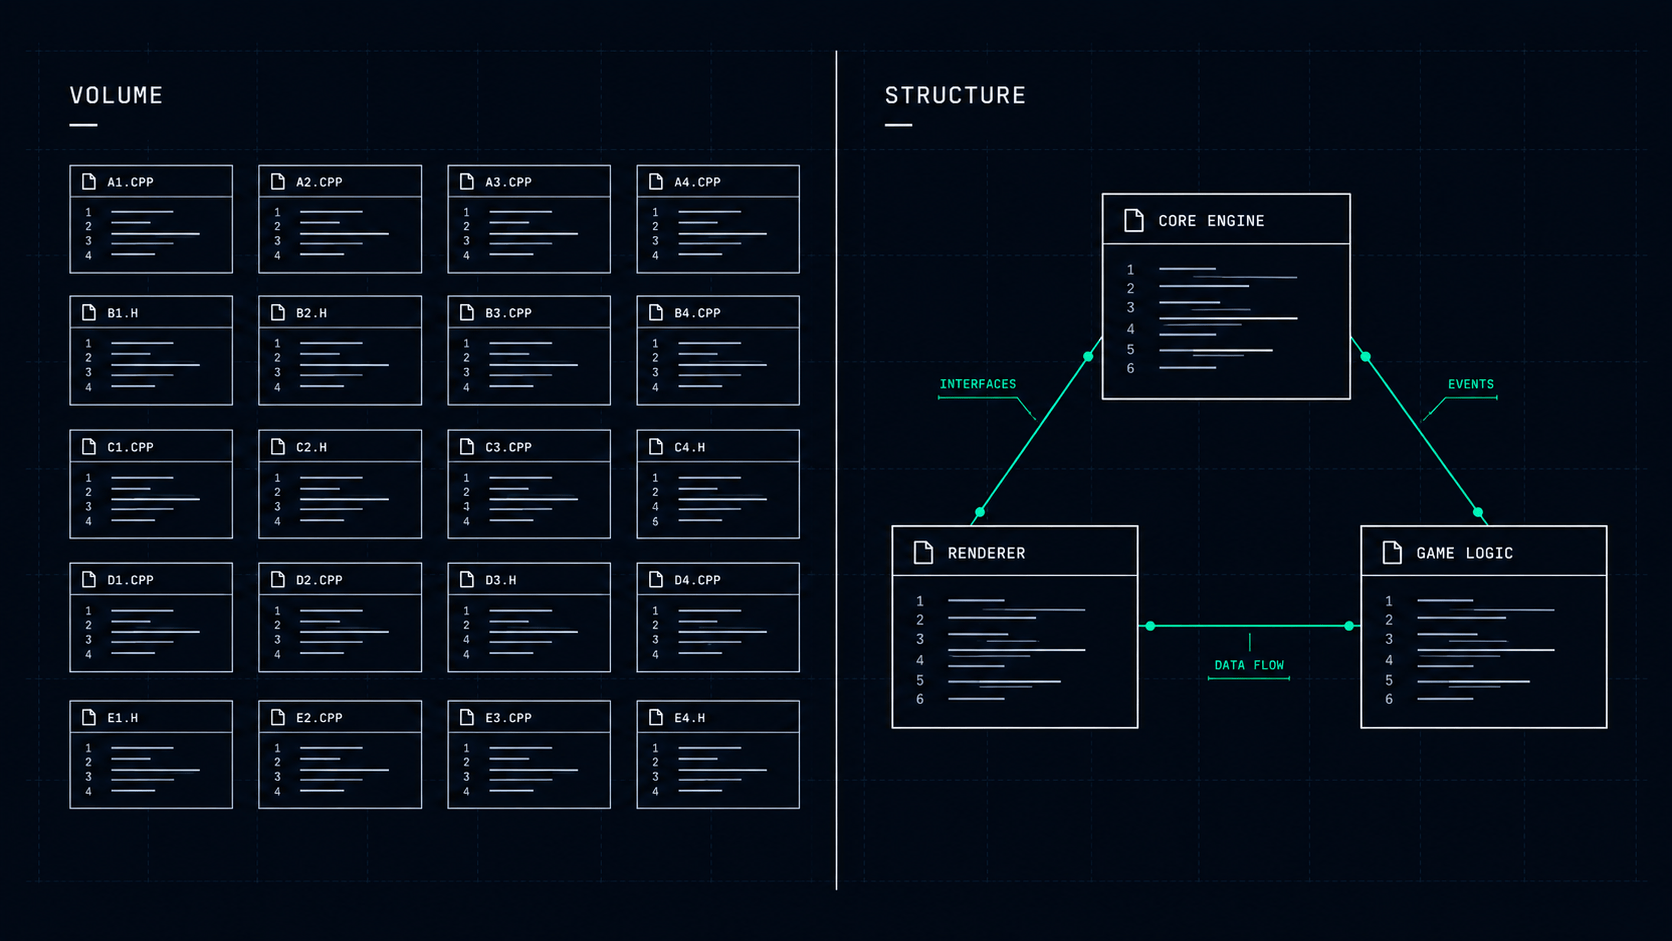
Twenty files where three components and a data flow would do. More source text, less structure.
Correct is not good enough
The phrase “correct is not good enough” captures the problem precisely. A program can compile. A program can pass tests. A program can satisfy a locally stated requirement. Yet it can still be the wrong contribution to a system.
Compilable means only that the program satisfies the syntactic and type related rules of the language. Tested means only that no error was observed in the selected cases. Even formal proof, powerful as it is, always operates relative to a specification. If the specification is incomplete, too weak or simply wrong, then a proof may be valid while the resulting system is still unsuitable for its real purpose.
Correctness is therefore not an isolated property floating above the system. Correctness is bound to a model. And the quality of that model is an architectural question.
Architecture is not merely the high level diagram of a large system. Architecture begins in small decisions: What is the right concept? Where does responsibility belong? Which variation is expected? Which assumption must be made explicit? Which state should be impossible? Which dependency is acceptable? Which invariant belongs in a type, in a concept, in a test or merely in documentation?
Architecture is the form in which a system expresses its truth.
A piece of AI generated code may solve the immediate task and still damage the architecture. It may introduce the wrong abstraction, stabilize the wrong dependency, hide a business rule in procedural code, duplicate a concept that should have been modeled once, or turn a structural invariant into a runtime convention. In such cases the code is locally correct but globally harmful.
This is why “it compiles” is not enough. This is why “the tests are green” is not enough. This is why “the AI generated it quickly” is not enough.
The measure is architecture.
The mathematical analogy: why the learning path matters
The analogy with mathematics is especially useful here. In school, we do not begin with abstract algebra, topology or measure theory. We begin with apples, stones, pieces of cake and visible quantities. A child first sees two apples and then three more apples. Before this becomes a formula, it is an experience: quantities can be combined. From this experience comes addition. From repeated addition comes multiplication. From dividing concrete things come fractions. From comparing parts come ratios. From patterns come arithmetic laws. From placeholders come variables. From variables come equations. From equations come functions. From functions come structures. Eventually, mathematics is no longer experienced as calculation, but as a language of precise relationships.
This path takes years, and it is not accidental.
It builds an inner coordinate system. A child who learns arithmetic does not merely learn how to produce results. The child learns plausibility. The child learns magnitude. The child learns transformation. The child learns that different representations can describe the same structure. The child learns that a rule applies under certain conditions and not under others. The child learns that proof is not the same thing as computation. The child learns that abstraction does not arise by skipping the concrete, but by penetrating the concrete deeply enough that its structure becomes visible.
No one would seriously argue that children no longer need mental arithmetic because calculators exist. Of course people do not need to perform long division by hand in daily life. Of course computers are better at large calculations. But a person with no feeling for numbers cannot judge the output of a tool. If someone does not understand that 19 times 21 must be close to 400, they may accept 3,990 if a machine displays it. If someone does not understand what a fraction means, they cannot reason about percentages. If someone has never transformed an equation, they cannot judge whether a symbolic result makes sense.
The calculator replaces mechanical calculation. It does not replace mathematical thinking.
AI is to programming what the calculator is to arithmetic, but with one additional danger: AI produces answers in a highly persuasive form. It does not merely display a number. It produces syntax, names, comments, tests and explanations. It looks competent even when the underlying model is weak.
Therefore the programming learning path must not be skipped. It must be improved.
Programming education is not just preparation for writing code manually. It is education in structure. When people learn programming, they learn how concrete operations become general rules. They learn how data and behavior relate. They learn that an interface is a contract. They learn that a type can carry meaning, not merely storage. They learn that a bug is often not an isolated accident, but evidence of a poor model. They learn that repetition in code usually indicates an abstraction not yet discovered. They learn that good architecture is not produced by diagrams alone, but by many precise decisions that form a coherent whole.
If we skip this path because AI can produce code, we create tool users without judgment. We create people who can ask for software but cannot assess the answer. That is not empowerment. It is dependence.
Why teaching only simplified languages is not enough
This also changes how we should think about introductory programming languages. Python and similar languages have real value. They are accessible, expressive and excellent for many tasks. They allow quick results and reduce early friction. But precisely because they simplify and hide many aspects of computation, they are not sufficient as the dominant educational answer in an age of AI.
Python already shortens the path. It already hides costs, lifetimes, value categories, ownership, memory layout, compile time constraints and many type related questions. That can be useful for motivation, but it also means that learners may not develop a deep model of what software systems are doing. They may learn to express behavior, but not necessarily to understand structure.
In an age without AI, this was already a limitation. In an age with AI, it becomes a larger problem.
If AI can already generate simple scripts, glue code, API wrappers and conventional application logic, then teaching people mainly the level of programming that AI is most likely to automate is not enough. It may indeed become possible, in many contexts, to replace a person who only writes ordinary Python level code with AI assistance. That does not mean the person is without value. But it does mean that the skill is closer to the surface that AI can imitate.
A modern C++ programmer is harder to replace for a different reason. Not because C++ syntax is harder, and not because difficulty itself is valuable. A modern C++ programmer works closer to the structural level of software: types, ownership, constraints, compile time guarantees, generic models, data flows and architecture. The value is not in typing more complicated symbols. The value is in using the language as a modeling space.
This is why the decision to teach simplified languages instead of modern C++ should be reconsidered. We do not need more education that hides complexity precisely at the moment when AI already hides too much. We need education that reveals the right complexity in the right order. We need learners to understand what a type means, what ownership means, what lifetime means, what compile time means, what an invariant means and how architecture can be expressed in code.
Modern C++ can serve that purpose if it is taught as modern C++, not as historical C with classes.
Modern C++ as a school of architecture
Modern C++ is often judged by an outdated image: raw pointers, manual memory management, include chaos, cryptic linker errors, unreadable template diagnostics and build system frustration. That image is not entirely invented, but it is incomplete and increasingly obsolete.
Modern C++ is a different language when taught through the standard library, RAII, std::vector, std::string, std::optional, std::variant, std::expected, ranges, concepts, templates and clear ownership rules. It is not a language that must punish beginners. It can be a language that makes the reality of digital systems visible.
Syntax itself can create architectural understanding. That may sound strange if syntax is seen as mere surface. But in C++, syntax often expresses binding, lifetime, ownership, type relationships, constraints, visibility and composition. Passing a parameter by value, by reference, by const reference or by forwarding reference is not merely a syntactic choice. It says something about ownership, cost, mutability and responsibility. Designing an algorithm for a concrete container or for a range is not merely a stylistic difference. It determines whether an operation is coupled to a data structure or expressed as a data flow. Expressing a requirement as a comment, as a runtime check or as a concept determines whether an error is documented, detected later or made impossible to express.
This is why modern C++ can be a school of architecture. It does not force complexity for its own sake. It allows precision. It makes visible what more forgiving languages often hide. It lets architecture be written into the code itself, not only into documents beside the code.
Interfaces, types, concepts, ranges and templates become architectural building blocks. They do not merely describe how something runs. They define which forms of the system are even valid.
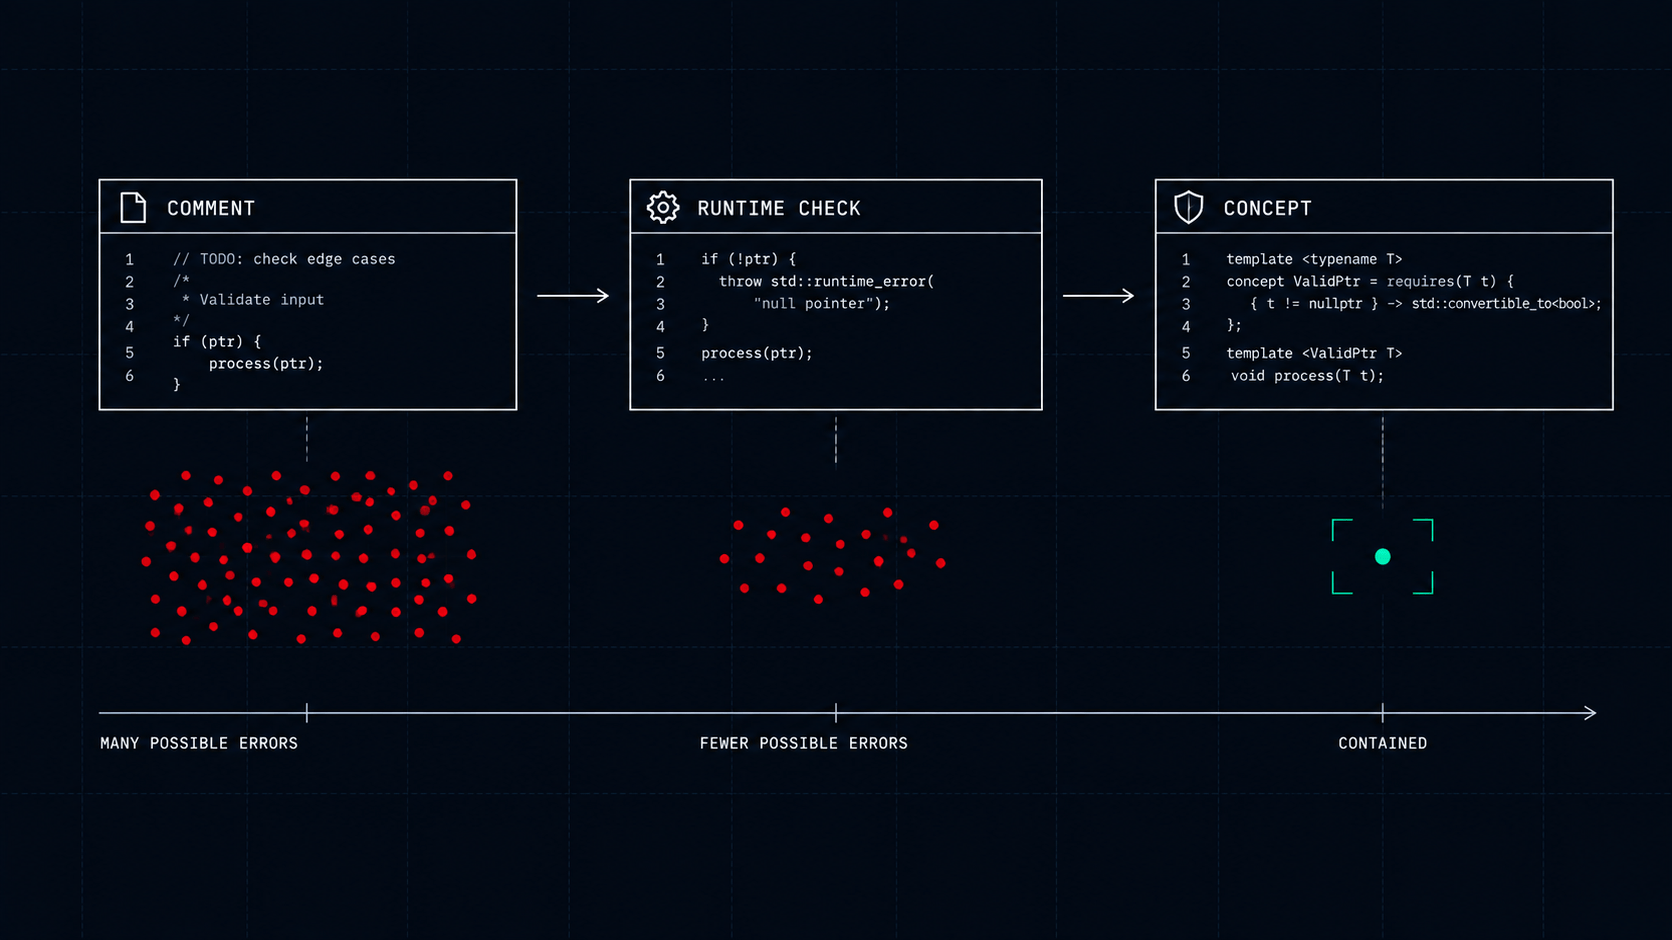
The same requirement, moved three times. Documented, then detected later, then impossible to express.
The compiler as a partner
In modern C++, the compiler is not merely a translator that turns source code into machine code. It is a partner. More precisely, it is a sparring partner. It checks assumptions, enforces predicates, rejects invalid combinations and constructs an executable program from well defined building blocks.
The developer no longer merely writes a sequence of instructions. The developer constructs a space of possible types, operations and data flows. The compiler moves through that space and ensures that only valid combinations are instantiated.
Concepts are central to this view. They are not merely nicer syntax for templates. They are predicates over type spaces. A concept states the conditions under which an operation is valid. It describes not only what a type happens to support, but what a type must mean within the model.
This moves a part of correctness into the language itself. The compiler does not verify everything. It cannot guarantee that the entire business domain has been modeled correctly. But what is expressible through types, concepts and constraints is checked with a rigor that no later test can replace. Within the formulated model, concepts can provide real correctness guarantees. Invalid forms are not tested and rejected at runtime. They are made unrepresentable.
That is a profound difference.
A test checks selected cases. A concept prevents an invalid form from becoming part of the program. A test may discover that a function fails for a wrong type. A constraint can make that call impossible. A test may show that a data flow works for selected inputs. A well modeled type space can ensure that only data flows whose operations and elements fit together are allowed to exist.
This is not magical correctness beyond specification. It is correctness inside the model. But inside that model it is hard, structural and real.
Type spaces, data flows and relations
Ranges deepen this architectural view. They move attention away from the concrete container and toward data flows, transformations and relations between types and operations. A data flow is no longer merely a loop over a container. It becomes a compositional description: filtering, transforming, projecting, aggregating.
In combination with concepts, ranges create relations over type spaces. Only those data flows are valid whose elements, operations and predicates fit together. One can view the type space as a space of possible relations. Data flows move through this space. Predicates determine which transitions are valid.
This is architecture made executable.
It is not merely documented. It is checked by the compiler. Not completely, not magically, not outside the limits of the specification, but reliably in the parts that are modeled. This creates a unique form of productivity. It is not the productivity of generating many lines. It is the productivity of making many wrong programs impossible.
Templates and variadic mechanisms extend this idea further. They allow variation to be expressed through generic structure instead of repetition. A well designed template architecture can replace large amounts of concrete source code without losing expressive power.
For me, this insight was not theoretical. It came from a real project in 2001 that was close to failing under its own growth. The code base was expanding explosively, and continuing to write more concrete code would only have accelerated the collapse. Out of necessity, I used templates to lift the already existing internal model, almost a framework within the code, into a generic structure. The effect was dramatic: the code base was reduced by about 90 percent, from roughly 100,000 lines to about 10,000 lines. More importantly, the project became controllable again and was ultimately completed successfully. The decisive productivity gain did not come from writing code faster. It came from expressing the right structure. Based on my own engineering observation, the factor can grow far beyond the earlier 90 percent reduction when variadic data flows, concepts as predicates and ranges as abstractions over concrete containers are used systematically. I cannot prove this with the same concrete project documentation as in the 2001 case, but the mechanism is visible in the code itself: many problems fall apart into small, precise building blocks, and the compiler combines these blocks repeatedly into concrete executable forms. Since these building blocks are often templates, and very often variadic templates, their reuse inside a single project can already become extremely high. For that reason, a ratio of 1 to 20 does not strike me as ambitious. It strikes me as pessimistic. The real productivity gain comes from semantic compression, not from textual expansion.
That is the opposite of AI generated boilerplate.
The false productivity of AI boilerplate
AI often generates code at the wrong level of abstraction. It answers the concrete request. It creates local implementations. It fills in visible gaps. It optimizes for plausible completeness. But modern C++ design often requires the opposite movement: away from local code and toward a generative structure that explains many cases at once.
An experienced modern C++ programmer does not first ask: how do I write this function? The deeper questions are different: What is the model behind these repeated cases? What properties must the involved types satisfy? Which data flows are valid? Which combinations must be impossible? Which invariants can the compiler check? Which error class should not be tested, but structurally excluded? What architecture is created by these choices?
These questions lead to productivity that does not dazzle. It may look slow at first. It may involve thinking, silence, sketching, deleting and looking out of the window. But when the right structure is found, code collapses. Repetition disappears. The system becomes smaller, stronger and more extensible.
AI often dazzles in the opposite way. It produces a lot of code quickly. It creates the appearance of acceleration. But if that code must later be compressed back into the architecture, if its duplication must be removed, if its implicit assumptions must be made explicit, if its runtime checks must become type constraints, if its concrete functions must become generic data flows, then the initial speed was partly an illusion.
The cost was merely delayed.
This does not make AI useless. It means AI must be used at the correct level. It can explain compiler diagnostics. It can generate test cases and negative examples. It can draft documentation. It can explore simple instances. It can help learners understand why a concept is not satisfied, why a range is not reusable, why a lifetime is too short or why an overload set behaves unexpectedly. It can be a useful assistant. It should not be mistaken for the architect of the model.

The initial speed was partly an illusion. The cost was merely delayed.
Why modern C++ may be easier to learn today
There is another outdated assumption that must be challenged: the idea that C++ is necessarily too difficult for learners.
Historically taught C++ was often difficult because it exposed learners to the wrong problems too early. Beginners were confronted with raw arrays, char*, manual new and delete, obscure build settings, linker errors, macros and implementation details before they had a stable conceptual model. That was not a law of nature. It was a didactic failure.
Modern C++ can be easier to learn when taught with the right tools and sequence. Learners can begin with values, types and invariants. They can use std::string, std::vector, std::array, std::optional, std::variant and std::expected. They can learn RAII before manual memory management. They can learn algorithms and ranges before iterator mechanics. They can learn concepts as named requirements. They can use templates as a way to model variation, not as a trick for experts.
AI also changes the learning situation. Compiler diagnostics that once discouraged beginners can now be explained. A learner can ask why a template instantiation failed, why a constraint was not met or why a value cannot be bound to a particular reference. This turns error messages into teaching moments.
Good IDEs matter just as much. If learners use tools such as C++Builder or Visual Studio, they do not have to begin with build systems, toolchains, include paths, package managers and linker configuration. These topics are important eventually, but they should not dominate the beginning. At the beginning, the focus should be on the language, the model and the architecture. A good IDE provides navigation, debugging, project structure, diagnostics and refactoring in an integrated learning environment.
Modern C++ plus a strong IDE plus AI assisted diagnostics is not the old beginner hostile C++. It is a powerful educational environment.
IDE access as educational responsibility
This leads to a practical and ethical conclusion: development environments for modern C++ must be free or easily accessible for learners.
Learners are not only school pupils and university students. Learners are also people in vocational retraining, career changers, professional developers being reskilled, programmers coming from other languages, experienced C++ programmers updating from older styles and professionals who now need deeper software understanding precisely because AI is changing the field.
Vendors of C++ systems should treat these groups as strategically important. They should worry less about every hypothetical case of license misuse and more about the generations of developers they can help form. Someone who learns with a particular IDE becomes familiar with its workflow, debugger, project model, libraries and development culture. Learners can become professional users, decision makers, advocates and customers.
Generous educational access is therefore not only charity. It is long term market strategy.
But the responsibility is deeper than market strategy. Providers of C++ development environments do not operate in an insignificant niche. C++ is part of the backbone of the modern IT world. Operating systems, databases, browsers, embedded systems, industrial systems, game engines, financial infrastructure, network components, compilers, runtimes and safety relevant systems depend heavily on C++ or on technologies that would be difficult to imagine without it.
Whoever provides tools for C++ participates in the maintenance of a technological foundation. That creates responsibility. The responsibility includes documentation, learning access, stable tools, good examples, understandable diagnostics, modern teaching material and a serious invitation to the next generation.
If C++ is part of the backbone of our IT world, then access to modern C++ education is not a minor issue. It is a question of technological resilience.
More qualification, not less
The central answer to AI should not be: people no longer need to learn programming. The answer should be: people need to learn programming better.
We need more qualification, not less. More model understanding, not merely more prompting. More architecture, not merely more generated code. More modern language, not historical burden. More accessible IDEs, not entry barriers through toolchains and licensing obstacles. More responsibility from vendors, not short term fear of misuse. More C++ as a school of precise thinking, not as a nostalgic test of endurance.
AI will remain useful. It will reduce routine work, explain errors, generate tests and accelerate many local tasks. But it does not replace the ability to think software structurally. It does not replace the path from concrete examples to abstraction. It does not replace the digital equivalent of number sense. And it does not replace the compiler as a precise partner that builds an executable program from well formed components while rejecting invalid structures.
The real credo is therefore simple: we must empower more people, not fewer. We must make modern C++ more accessible, not push it out of education. We must open IDEs as learning spaces, not protect them behind unnecessary barriers. We must use AI as a tool, but strengthen the judgment needed to evaluate its output.
In a world where code becomes easier to generate, the decisive qualification is the ability to distinguish good code from code that merely looks correct.
And that ability has a name: architectural understanding.
End of Volker Hillmann’s article.
Whole Tomato’s note
There are two important takeaways in this piece when you build tools for C++ developers instead of writing about them.
The first is where Volker puts AI. Explaining a compiler diagnostic, drafting a negative test case, exploring one instance of a problem. All of it is useful but none of it is the same as owning the model. We got to roughly the same position, which is why the AI features we ship only see the code you hand them and don’t go looking for more.
The second is his section on IDE access, and it addresses companies like ours. His argument is that anyone shipping tools for a language with this much infrastructure dependability should take on some responsibility for the people still learning it. Licensing shouldn’t be the thing standing between a learner and a modern C++ environment. And to us that’s a fair challenge.
Note: Visual Assist users in the academe may be eligible for education licenses. More info here.
About the author
Volker Hillmann is a mathematician and software architect from northern Germany, working at the intersection of formal mathematics and applied computer science. His focus is databases, data security, and software architecture, with a consistent emphasis on modern C++. He has been programming in Turbo C since 1988 and Turbo C++ since 1991, has lectured widely on C++ and architecture, and has been self-employed since 2001. He has been an Embarcadero MVP since the mid-2000s. His livestreams cover modern C++ across compilers rather than any single toolchain.
Originally published by Volker Hillmann on LinkedIn on 21 June 2026 as “Correct Is Not Good Enough: Why AI Makes Programming Education More Important, Not Less.” Republished with permission. Read the original.